
Equal Variance Assumption in ANOVA and t-Tests
The equal variance assumption (homogeneity of variance, or homoscedasticity) is a core requirement of the two-sample t-test and analysis of variance (ANOVA). Both procedures test whether population means differ. When the assumption holds, the pooled error variance is unbiased and the reported p-values remain trustworthy.
Key Takeaways
- The equal variance assumption requires compared groups to share a common population variance.
- ANOVA and the two-sample t-test are robust when sample sizes are equal or nearly equal.
- Violations usually make p-values look smaller than they should.
- A log or Box-Cox transformation often corrects variance that grows with the mean.
- Observed differences in variance can be a process-improvement finding, not only a testing problem.
What Is the Equal Variance Assumption?
The equal variance assumption states that the populations being compared have the same variance, or a variance that is close enough for the procedure to remain valid. In a two-sample t-test, that means the two populations share one common variance. In one-way or multi-factor ANOVA, it means every group shares that common variance.
When the assumption is satisfied, the pooled estimate of error variance is unbiased. The t statistic or F statistic then follows its intended reference distribution, and the p-value correctly describes the Type I error rate under the null hypothesis of equal means.
In statistical language this property is called homoscedasticity. The opposite—unequal group variances—is heteroscedasticity. You will also see the phrase homogeneity of variance in software menus and textbooks. These terms refer to the same equal variance assumption.
Why the Equal Variance Assumption Matters
Unequal variances change the overall estimate of error variance. That distortion moves into the t or F statistic and then into the reported p-value. In typical applications, the reported p-value underestimates the true Type I error rate. In other words, the actual chance of incorrectly rejecting the null is larger than the number on the output.
The practical risk is overconfidence. A result can appear statistically significant when it is only marginally so, especially when the p-value sits near 0.04 to 0.06.
There is a second, more useful implication. A failed equal-variance check often means the process itself changed in spread, not only in location. If reducing variation in Y is a project goal, that signal deserves study on its own.
| Situation | Practical rule |
|---|---|
| Sample sizes equal or nearly equal | ANOVA and the two-sample t-test are robust. The equal variance assumption can be relaxed substantially. |
| Sample sizes unequal, largest SD / smallest SD ≤ 2 | Usually no material problem for mean comparisons. |
| Sample sizes unequal, ratio greater than 2 | Use Welch’s t-test, a transformation, or investigate the variance difference directly. |
| Balanced samples, ratio greater than 4 | Treat the departure as serious. Check residuals and consider an alternative procedure. |
| Variance increases as the mean increases | Apply a log or Box-Cox transformation, then re-check residuals. |
Key Considerations When Checking Equal Variances
Do not treat the equal variance assumption as a pass/fail gate that stops analysis. Use the following six considerations as a decision framework.
1. Robustness when sample sizes are equal
Both the two-sample t-test and ANOVA tolerate moderate unequal variances when sample sizes are balanced. Equal n is the strongest protection you have. If the design is balanced, a modest variance difference rarely invalidates the mean comparison.
2. Alternative procedures
The two-sample t-test can be run without assuming equal variances. That version is Welch’s t-test, and it is the default in Minitab. Welch’s procedure does not pool the two sample variances into one common error term.
Non-parametric alternatives exist for the t-test and for ANOVA. Those methods still require the underlying distributions to share a similar shape. Stating that two distributions have the same shape is close to stating that they have the same variance. Because parametric tests are uniformly more powerful under approximate normality, they remain the first choice when the data support them.
3. Data transformations
If sample variance rises with the size of Y, a log transformation or a Box-Cox power transformation often stabilizes spread. After transforming, re-plot residuals against fitted values. The equal variance assumption applies to the analysis scale, not to the original units if you transformed.
4. Effects of unequal variances
Unequal variances affect the pooled error-variance estimate. That bias flows into t or F and then into p-values. The p-value you see is typically smaller than it should be. Concern is highest when the result is only marginally significant. A p-value of 0.001 is rarely overturned by a moderate variance imbalance; a p-value of 0.049 can be.
5. Parametric tests versus non-parametric tests
Non-parametric tests are not a free pass around variance. They assume comparable shapes. If that assumption fails, the non-parametric p-value is not automatically more honest. Prefer the parametric t-test or ANOVA when normality is reasonable, and prefer Welch when variances clearly differ and sample sizes are unequal.
Pugh Matrix Template for Excel and Google Sheets — Complete 5-Workbook Suite
6. Differences in variance can be desirable
A core goal of process improvement is reducing variation in the critical-to-quality characteristic (CTQ, or Y). The two-sample t-test and ANOVA detect mean shifts. If the data also show a shift in spread, that finding can be more important than the mean test you planned. Study whether the variance change is consistent, assignable, and actionable.
Equal Variance Assumption and ANOVA
ANOVA is a generalization of the two-sample t-test, so the same equal variance assumption applies. In a balanced design—equal observations per cell—the F-test is robust. In an unbalanced design, inspect the ratio of the largest sample standard deviation to the smallest, then decide whether to transform, to use a Welch-type adjustment, or to treat the variance pattern as the result.
The assumption is about residual variances, not necessarily the raw Y values in a multi-factor model. Organize residuals by factor combination and compare spread. Residual-versus-fits and residual-versus-factor plots show whether variance tracks the mean or a particular factor level.
For one-way ANOVA this check is straightforward. For two-way ANOVA it remains practical. For many factors, grouping residuals by every cell becomes cumbersome. In that case, look for extreme residual outliers and for systematic fans in residual plots. Those plots still reveal main effects on variability and correlation between residual variance and the response.
How the Equal Variance Assumption Fits into DMAIC
In a Breakthrough / Lean Six Sigma project, the equal variance assumption shows up in Analyze and again in Improve. The same statistical tools serve different questions in each phase.
Analyze Phase
In Analyze, the Black Belt isolates leverage variables that move the CTQ. For a continuous Y, that work uses tools that detect differences in means, differences in variances, and patterns in either. The two-sample t-test and ANOVA are the primary mean tests. Their assumptions match because the two-sample t-test is a special case of one-way ANOVA.
Test for equal variances. If the test fails, check the ratio of the largest sample standard deviation to the smallest. If sample sizes are equal or nearly equal, there is usually no problem unless that ratio exceeds 4. Even when sample sizes are not nearly equal, there is usually no problem unless the ratio exceeds 2.
More important: you used these tools to detect a change in the mean of Y, and you also detected a change in the variation of Y. That second finding may help you reduce the variation of Y, which is often the higher-value outcome.
Try a data transformation when sample variances increase with sample means. Remember that reported p-values may be slightly too small if variances are unequal. If a t-test or ANOVA is only marginally significant, the actual p-value may be marginally insignificant. Always weigh practical significance with statistical significance before you lock a conclusion.
Improve Phase
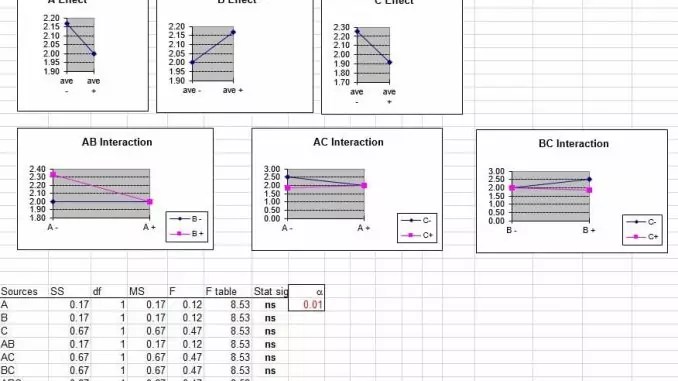
In Improve, designed experiments change leverage variables together and measure the effect on the CTQ. Significance of main effects and interactions is often judged from an ANOVA table, a Pareto chart of effects, or a normal plot of effects. All of those displays depend on the error-variance estimate, which unequal residual variances can distort.
Fortunately, most designed experiments are balanced. Equal sample sizes let you relax the equal variance assumption. Still, check for radical departures. Remember that it is the variances of the residuals that are assumed equal, not the variances of the raw Y values.
For a one-way or two-way model you can group residuals by term and estimate each group’s variance. Beyond two factors that grouping becomes hard. An efficient alternative is to scan residuals for extreme outliers and to plot residuals against each factor and against the fits. Those plots show whether any factor affects residual spread and whether residual variance tracks the response.
P-values in the ANOVA table may be slightly underestimated. The cutoff line on a Pareto chart of effects may sit slightly higher than it should. A marginally significant effect could be marginally insignificant after that correction. In every borderline case, ask whether the effect is large enough to matter in the process before you change the standard operating condition.
How to Test for Equal Variances in Minitab
Minitab’s homogeneity of variance procedure is the standard check for the equal variance assumption across two or more samples.
- Go to Stat > ANOVA > Test for Equal Variances.
- In Response, enter the column that contains the Y data.
- In Factors, enter the factor or factors that define the groups. For a two-sample t-test, the factor is an indicator of which sample each Y value belongs to.
- Click OK.
- Read the p-values from Bartlett’s test, Levene’s test, or the F-test, and review the confidence intervals for the sample standard deviations.
Prefer Levene’s test when normality is in doubt; it is less sensitive to heavy tails than Bartlett’s test. Do not stop at the p-value. The interval plot of standard deviations shows whether one group drives the result and whether the largest-to-smallest ratio stays inside the robustness guidelines above.
If the equal variance assumption is untenable, choose the path that matches the data: Welch’s t-test for two groups, a variance-stabilizing transformation, residual diagnostics in a designed experiment, or a focused study of why spread changed.
Frequently Asked Questions
What is the equal variance assumption?
It is the requirement that the populations being compared have the same variance. It supports the pooled-variance two-sample t-test and classical ANOVA. Analysts also call it homogeneity of variance or homoscedasticity.
What happens if the equal variance assumption is violated?
The reported p-value is typically smaller than the true Type I error rate. Results can look more significant than they are. The problem is most acute when sample sizes are unequal and the ratio of standard deviations is large.
Are t-tests and ANOVA robust to unequal variances?
Yes, especially when sample sizes are equal or nearly equal. A practical guideline is that the largest standard deviation should not be more than twice the smallest when sample sizes differ substantially, or more than four times the smallest when sample sizes are balanced.
Should I always transform the data when variances are unequal?
Transform only when variance clearly increases with the mean. Logarithmic and Box-Cox transformations are the usual remedies. Always inspect residual plots after the transformation.
When should I use a non-parametric alternative?
Use a non-parametric test when the data are markedly non-normal and the sample sizes are small. Those tests still assume similar shapes across groups, so they do not remove the spirit of the equal variance assumption.
Does a significant difference in variance matter?
Yes. Reducing variation is often more valuable than shifting the mean. Study differences in variance as process insights, not only as obstacles to a mean comparison.
How does the assumption apply in designed experiments?
Most designed experiments are balanced, so the equal variance assumption can be relaxed. Focus residual diagnostics on residual variances rather than raw response variances. Plot residuals against fits and against each factor.
Treat the equal variance assumption as a diagnostic, not as a rigid stop sign. Apply t-tests and ANOVA with the robustness rules in view, transform when variance tracks the mean, and convert a failed variance check into an opportunity to reduce process variation.
Be the first to comment